The token gap
Token demand grows about 10x a year. Compute supply grows 3.4x. The difference has to come from the serving layer, and that is where we work.
Last October we were in the audience at OpenAI’s DevDay. At one point Sam Altman stepped out in front of a wall of names: the developers who had processed the most tokens through the API. Ten billion tokens over a lifetime of building earned your name on that wall and a public tribute from Sam Altman himself.

Eight months later, this June, we watched a single user on Umans AI run nearly eleven billion tokens in a single day.
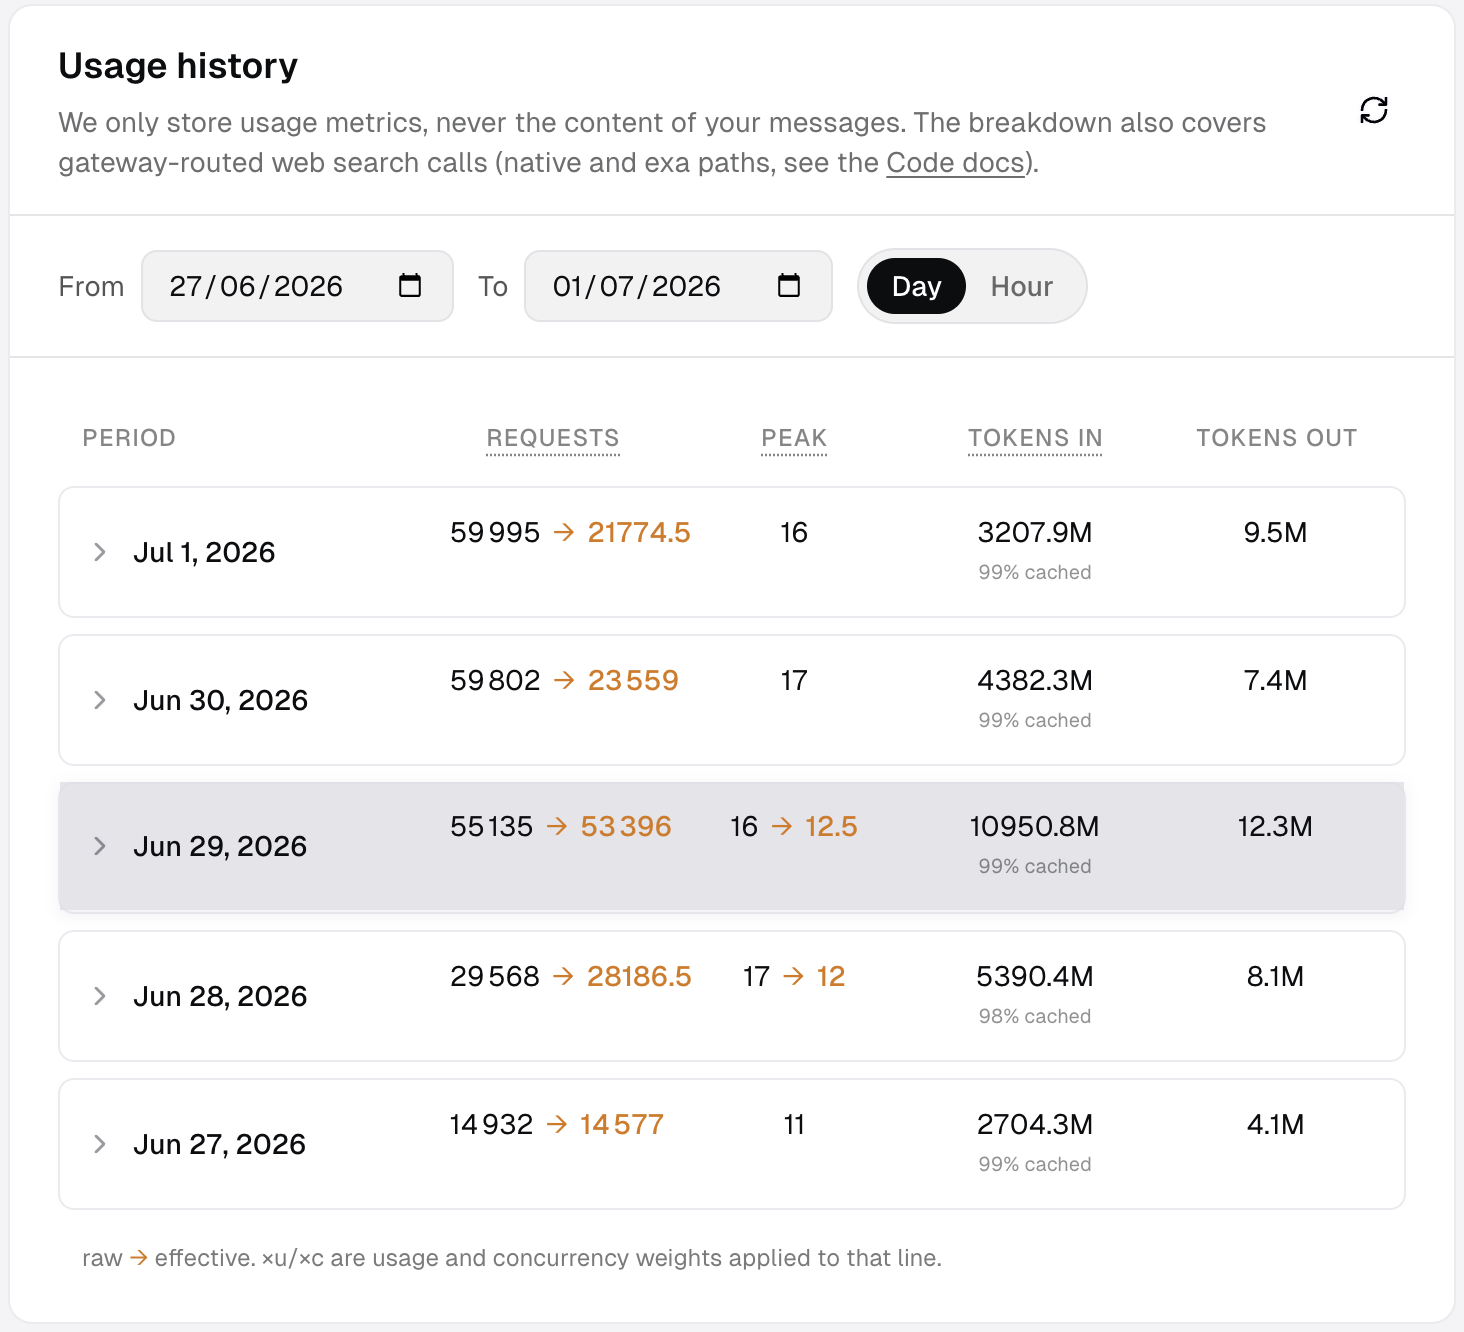
That is how fast demand for tokens is moving. The rest of this article is about what that means at market scale: how fast demand grows, why compute supply cannot keep up, and why closing that gap is the work we chose at Umans AI.
1. Token demand grows faster than compute supply
Eleven billion tokens a day from one user won’t surprise anyone for long. Demand for tokens grows about an order of magnitude every year. Measured growth rates range from 7x to 30x per year depending on the vantage point, from Google’s own disclosures to the traffic through gateways like OpenRouter and Vercel, and the best market-wide estimate sits around 10x. The world’s AI compute supply, counting both more chips and better chips, grows 3.4x per year on Epoch AI’s measurements.
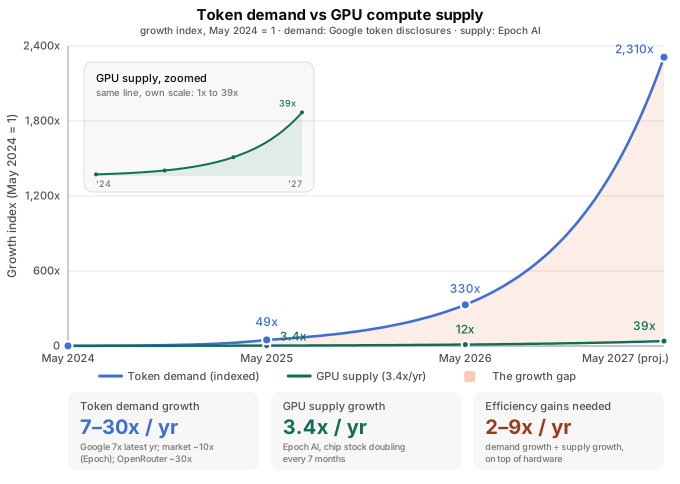
Run the two rates forward from today’s serving base and they cross. Somewhere between late 2026 and mid 2027, on central estimates, demand passes what the installed base can serve at today’s efficiency, and the gap widens from there.
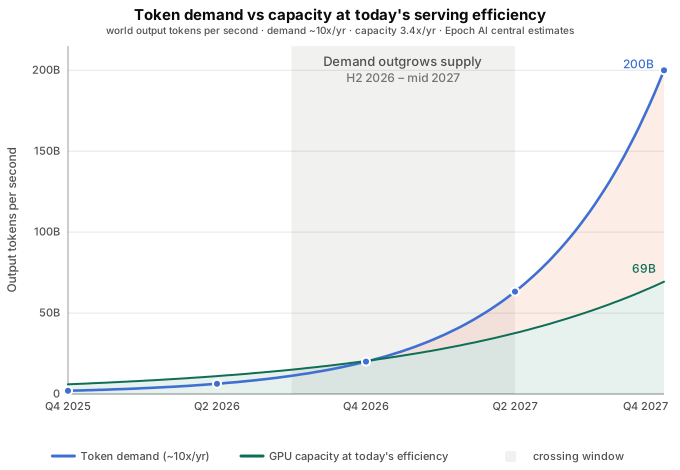
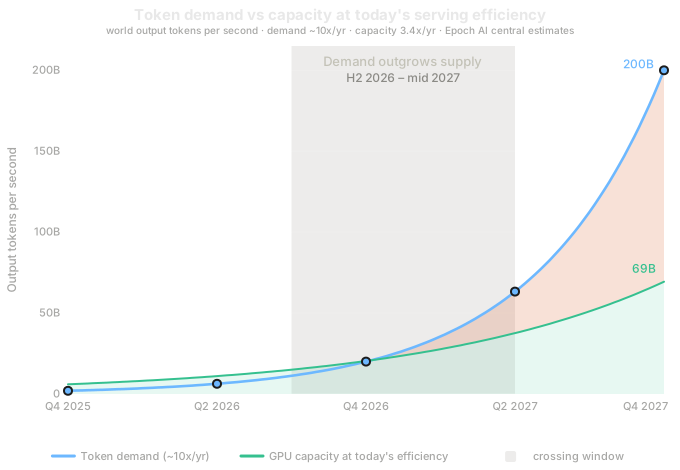
Those two rates do not close on their own. For demand to remain servable, tokens delivered per chip must improve 2x to 9x every year, on top of all hardware progress. If they do not, the gap closes the only other way a market can close it: through price, and tokens go to whoever can outbid everyone else for compute.
2. Why hardware cannot catch up alone
The supply curve is not slow for lack of money or ambition. It is slow because it runs through a chain of physical choke points, and the chain narrows toward single companies.
One company on earth builds the lithography machines every advanced chip depends on, and it ships a few dozen per year. One foundry, TSMC, fabricates over 90% of leading-edge chips, and effectively 100% of AI accelerators: Nvidia, AMD, Google and Amazon design their chips and own no factories; TSMC builds for them all (appendix B). Its challengers trail on the one metric that decides everything: yield, the share of chips that come out of the factory working (appendix A). Behind fabrication sits a second, independently constrained step: advanced packaging, the assembly that bonds compute dies and their memory into one finished part, sold out industry-wide for years.
A new fab costs tens of billions and takes years to qualify. A gigawatt data-center site takes about two years to energize, behind lengthening grid queues.
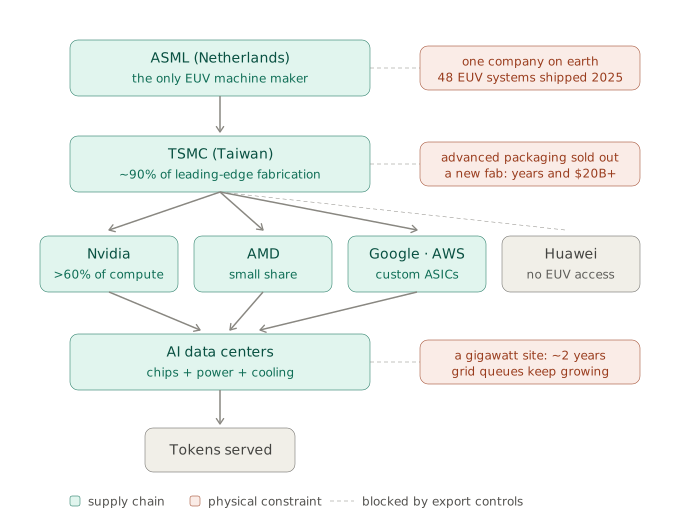
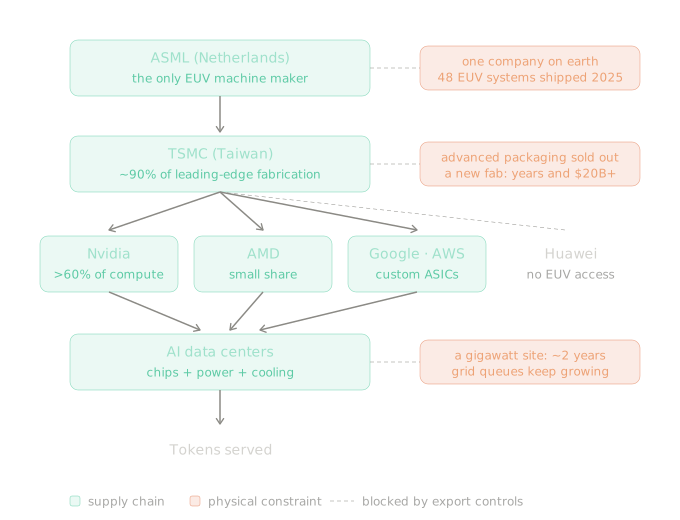
This chain already runs at maximum effort, under the industrial policy of every major power. 3.4x per year is what physical manufacturing delivers at full capacity. The remaining 2x to 9x must therefore come from the only layer that ships in weeks instead of years: the engineering that turns GPU time into delivered tokens. The headroom there is real. NVIDIA’s own AI factory numbers show software improvements alone cutting token cost 5x in two months on the same hardware.
3. Agentic work is where the economic value is
In a market in tension, every GPU-hour is an allocation decision. Compute that serves low-value tokens is compute taken away from high-value ones, so the scarcer compute gets, the more it matters where it goes.
Where it is worth going is where AI does actual work. Agentic tokens write the code, run the analysis, complete the task: they are what makes automating high-value work possible, and that is what the whole chain exists to produce. A cheap token that fails the task is not cheap; it is scarce compute wasted. A more expensive token that finishes the job is the better allocation.
So the problem worth solving is precise: make the tokens that do valuable work abundant and cheap to produce. That is efficient agentic inference, and it is why we focus there.
4. Where we sit: efficient agentic inference
Hardware alone can’t keep up with demand; the difference has to come from how the GPUs are served. That difference is what we work on, for the tokens that do the work.
Focus is structural. Pure-play agentic inference means every engineer-hour compounds into a single asset: the delivered-token frontier, how many tokens a GPU produces at each level of per-user speed. And agentic inference is its own discipline. Look back at the usage screenshot that opened this article: 99% of those eleven billion tokens were served from cache. That is what agentic work looks like from the serving side. An agent rereads a large, growing workspace to emit a few hundred tokens, so serving it well is a prefill and cache problem, a different problem from chat, and the one our stack is built for.
The lineup follows from that. We serve a short list of frontier models, the ones capable of valuable work, and change it carefully. When a model is missing a capability the work needs, we can add it ourselves: we built a vision variant of DeepSeek V4 Flash and tested it with our community in Labs.
The rest is execution. We serve trillions of agentic tokens a month, add models the day they are released, at speeds above what the model maker itself publishes, and the same GPUs deliver more of them each month as the stack improves. Tokenomics, behind the scenes walks through the measurements.
5. Efficiency is what democratization runs on
On the current trajectory, demand outgrows what hardware alone can serve; the figures in section 1 show it. In that world, serving efficiency is what keeps valuable tokens affordable, and automated work accessible beyond the few who can outbid everyone else for compute. Efficiency is what democratization runs on.
The wall at DevDay celebrated ten billion tokens as a lifetime of work. A few months later that is one motivated user’s Monday, and the curve does not stop there. Keeping that curve affordable to ride is the problem we chose.
Appendix A: yield, up close
Chips are not made one at a time. They are printed together on a wafer, a thin disc of silicon, which is then cut into individual dies; on some dies the printing lands perfectly, on others a microscopic defect kills the circuit. Yield is the share of dies that come out working, and it decides the economics because the wafer costs the same either way. Processing a 2nm-class wafer runs roughly $25,000 to $30,000, whether 40% of its dies work or 65% do. So the cost of a working chip is the wafer price divided by the number of good dies: out of every hundred dies, the same wafer yields 40 sellable chips in one case and 65 in the other, and each of those 40 costs about 60% more than each of the 65.
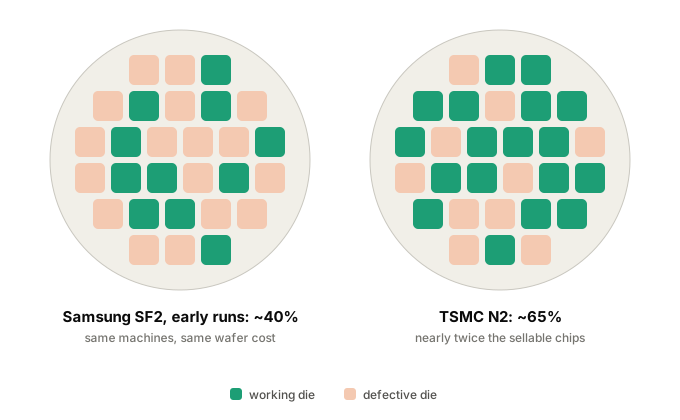
The gap is hardest on AI chips. Defects land roughly at random across the wafer, so the bigger the die, the more likely it catches one, and AI accelerators are among the biggest dies made. A yield gap that is painful on a phone chip becomes disqualifying on GPU-sized silicon.
And yield compounds. It improves by tracing defects across millions of dies back to individual process steps, so the foundry with the most volume learns fastest, keeps the highest yield, and wins the next round of volume. Every foundry buys the same lithography machines; the difference lives in the thousands of steps around them, institutional memory that does not ship with the equipment. The current standings, roughly 65% for TSMC’s N2 against 40 to 60% for Samsung’s 2nm runs and around 55% for Intel’s 18A, have kept the same ordering for years. A challenger’s best year makes it a credible second source, not a dent in the concentration, which is why the 3.4x supply line in section 1 is physics rather than pessimism.
Appendix B: who actually builds the chips
Nvidia owns no factories. It designs the architecture, the circuits and the software, then sends the design to TSMC, which manufactures the dies and, mostly, packages them too; the memory stacks come from SK Hynix, Samsung or Micron. That is the norm, not the exception: AMD spun off its factories in 2009, Google, Amazon, Apple and Qualcomm never had any, and even Intel now fabricates some of its own chips at TSMC. Designs are abundant and fast to iterate; factories are scarce and slow to build. Huawei is the exception that proves the rule: it designs its own accelerators, but, cut off from the lithography machines by export controls, it has to build them on older equipment at China’s SMIC.
This is also why high margins do not fix the shortage. Nvidia cannot turn its profits into more chips any faster than TSMC and its suppliers can expand; its growth is rented from someone else’s factory, booked as capacity like everyone else’s, just in bigger blocks and earlier. And it is why the supply-chain figure in section 2 narrows the way it does: many designers, one manufacturer, one lithography maker.
Sources
- Demand growth: Google’s I/O token disclosures, 2024 to 2026 (7x in the latest year); public gateway traffic from OpenRouter and Vercel’s AI Gateway (up to ~30x per year); Epoch AI, Is a compute crunch coming?, May 2026 (~10x market-wide, and the crossing-window estimates).
- Supply growth: Epoch AI, Global AI computing capacity is doubling every 7 months, January 2026; token conversion calibrated on SemiAnalysis InferenceX.
- Choke points: ASML shipment reports, 2025; TechInsights and industry yield analyses of TSMC N2, Samsung SF2 and Intel 18A, 2026.
- Memory: Bloomberg, Asia Centric, How AI created an unprecedented memory chip crisis, February 2026; Bloomberg, Nvidia customers notified about AI-related price hikes above 15%, August 2026.
- Software efficiency: NVIDIA, AI factory economics.
- Umans AI figures: Tokenomics, behind the scenes, August 2026, production metrics alongside SemiAnalysis InferenceX and Artificial Analysis public data.
- Vision augmentation: DeepSeek-V4-Flash-0731-Vision on Hugging Face.